What is the authoritative corpus?
Define included sources, ownership, versions, freshness, access and deletion before indexing.
Corporate AI training · Onsite & live online
Based in Bengaluru · delivering across India
Live-online RAG training · Technovids Bengaluru
Build retrieval systems that can be measured: from document preparation and search to citations, answer evaluation, access control and production handoff.
RAG Training in Bangalore is developer-focused training on Retrieval-Augmented Generation from Technovids, headquartered in HSR Layout, Bengaluru. It covers ingestion, chunking, embeddings, vector and hybrid retrieval, metadata, reranking, grounded generation, citations, evaluation and operational controls. Participants learn to diagnose retrieval and answer failures separately. Public cohort dates and fees are confirmed before enrolment and classes run live online; private corporate delivery can be scoped for Bangalore teams. It is a RAG course for Bangalore developers, taught live online.
Updated
Scope boundary: The course does not guarantee hallucination elimination, retrieval accuracy or production readiness. Data, model, embedding, store, API cost and projects are confirmed for the selected delivery; the standard course runs 70 hours.
A fluent answer cannot recover evidence the retrieval layer failed to find.
Define included sources, ownership, versions, freshness, access and deletion before indexing.
Choose parsing, structure, chunks and metadata according to questions and evidence boundaries.
Build query–evidence judgements before comparing embeddings, search or reranking.
Measure source support, completeness, refusal and citation correctness separately from style.
Labs make the evidence flow visible so participants can locate failures instead of changing models blindly.
Load approved files and preserve useful structure, provenance and version metadata.
Compare chunk boundaries, overlap and metadata for representative questions.
Compare semantic, lexical and combined search for the same judged queries.
Apply metadata permissions and reorder candidates with a deliberate quality–latency trade-off.
Generate an answer from retrieved evidence and expose source references.
Track retrieval, answer, latency, cost and failure categories across a test set.
A RAG specialist course is useful when retrieval is the main engineering gap.
This page
Build and evaluate the ingestion-to-answer pipeline in depth.
Best for: Developers and data engineers working on knowledge systems
Learn wider LangChain application patterns including retrieval and agents.
Best for: Developers standardising on LangChain
Use retrieval as one tool within controlled multi-step agent workflows.
Best for: Developers building tool-using agents
Combine RAG with agents, MCP, APIs, deployment and operations.
Best for: Developers needing end-to-end production capability
The narrower course offers more retrieval depth; the full programme covers more of the surrounding system.
| Decision point | RAG Training Bangalore | Production AI Engineering |
|---|---|---|
| Primary scope | Ingestion, retrieval, grounding and RAG evaluation | RAG, agents, MCP, APIs, deployment and LLMOps |
| Best fit | Teams with a retrieval or knowledge-system goal | Developers building complete AI applications |
| Duration | 70 hours, live online | 48 live hours over 12 weekends |
| Typical output | Measured RAG pipeline and evaluation pack | Five integrated portfolio project patterns |
A good result shows retrieval and answer evidence separately.
Documents, versions, chunks, metadata and access expectations are explicit.
Queries have judged evidence and retrieval changes can be compared.
Material claims can be checked against cited passages and refusal rules.
Security, freshness, scale, latency, cost and monitoring gaps are documented.
We confirm the route before training starts, so everyone practises at the right level and nobody mistakes a tutorial demo for something ready for production.
Confirm whether you need a public course, a private team workshop or a wider engineering programme.
Agree the coding level, accounts, model access, practice data, repository and any security limits.
Dates, length, topics, exercises, format, fees and what is included are set out before you book.
Short explanations, then building, testing, debugging and feedback from the trainer.
Everyone leaves with reviewed work, its known limits and a plan for more practice or a real build.
The selected format determines the corpus, implementation and evaluation depth.
Sources, parsing, versions, metadata, permissions and refresh assumptions.
A bounded ingestion, retrieval and grounded-answer workflow.
Queries, judged evidence, answer checks, failures and changes.
Access, privacy, scale, freshness, latency, cost and monitoring questions.
In every exercise, you can see who has access, how the work is tested, how failures are handled and where a person decides.
Labs use approved model access, safe documents and practice connections. Passwords, keys and private data never go in prompts or source control.
A demo that works is tested on normal, hard and failing cases before anyone calls it reliable.
Permissions, input checks, timeouts, budgets and approval steps limit what an agent or connection can do.
A qualified person checks sources, outputs, tool calls and important actions before release or use.
The lab stack is confirmed before delivery; framework and provider integrations are checked against current first-party documentation.
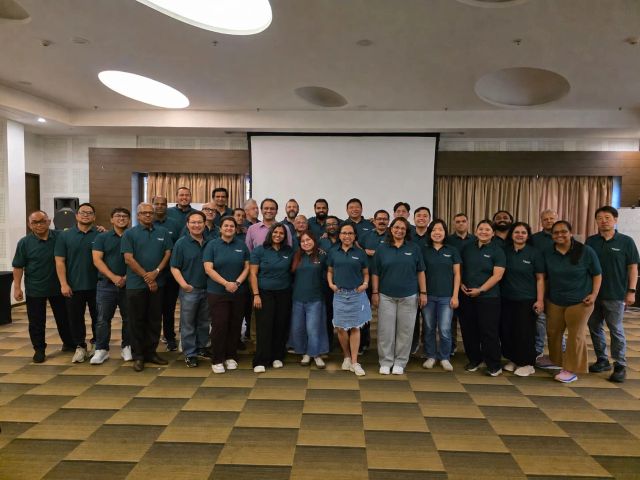
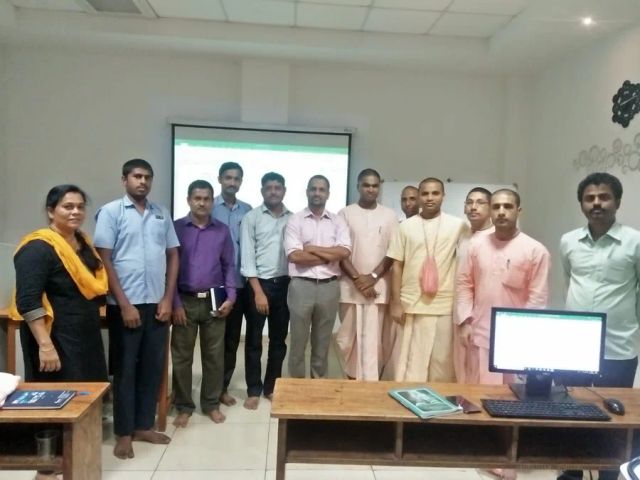
Real photos from Technovids training sessions. They show how we teach, not a promised result for your group.


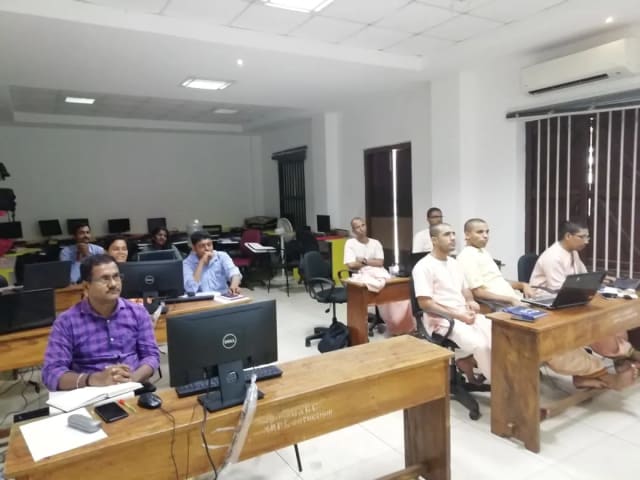


Photos from real Technovids sessions with teams in Bangalore. They show how we teach, not a promised result for your group.
We choose the trainer once we know who is attending, how deep the subject goes and how it will be delivered.
Co-founder & Lead Instructor, Technovids Consulting
Pankaj is a co-founder and the lead instructor at Technovids Consulting. His programme work spans practical AI adoption, AI engineering, evaluation, responsible production AI, data analytics and corporate learning design, with an emphasis on hands-on exercises connected to workplace tasks.
Expertise:
AI & Machine Learning Trainer, Strategist and Consultant
Junaid is an AI and machine-learning trainer, strategist and consultant with more than 22 years of training experience. His work combines enterprise AI education, business-centred adoption, responsible AI practices and applied solution design, helping professional audiences connect AI concepts to real organisational needs.
M.E. in Computer Engineering, specialising in Artificial Intelligence · author of programming books on Python, Java and C++
Expertise:
Technical Trainer & Curriculum Architect
Pradeep is a technical trainer and curriculum architect with more than 20 years of experience across enterprise technology, cloud infrastructure and advanced AI systems. He designs practitioner-focused programmes, labs and assessments covering AI, LLM systems, Python and machine learning, translating complex technical subjects into structured learning experiences.
Bachelor of Engineering in Electrical Engineering · instructor-led, virtual and blended delivery
Expertise:
Your proposal names the trainer. Not every trainer shown here teaches every programme.
To book a trainer for your team, call +91 86183 46384 or email [email protected].
Updated
Feedback shared with permission and photos from our sessions show how Technovids trains. They are not a promised result from this course.
Hands-on training for people and teams in AI, data, cloud, productivity and workplace skills.
What people we trained found useful in their day-to-day work.
The AI training from Technovids helped me gain a better understanding of Generative AI, prompt engineering, and practical AI use cases for software development. The course was clear, interactive, and focused on real-world applications. It gave me confidence to explore AI tools more effectively in my work.
Technovids conducted the AI training in a very effective and engaging manner. The sessions were practical, easy to follow, and focused on how AI can be used in real software engineering and business workflows. It was a valuable program for understanding the current direction of AI adoption in the industry.
The AI training delivered by Technovids was practical, structured, and relevant for software professionals. The sessions connected AI concepts with real industry use cases, making it easier to understand how AI can be applied in development, automation, and productivity improvement. It was a valuable learning experience.
I had been trying to transition from traditional backend development to Generative AI, but self-learning was getting overwhelming. The AI Engineering course at Technovids gave me the exact structured roadmap I needed. The modules on LLM architectures and practical prompt engineering are brilliant. It’s not just theory; you actually build functional AI applications. Highly recommend this for working professionals looking to upgrade their tech stack.
What I loved most about the Technovids GenAI program is how up-to-date the curriculum is. Instead of outdated practices, we learned to integrate the Model Context Protocol (MCP) and practically apply tools like Claude and Cursor for AI-assisted coding. It felt like I was learning the exact skills that top tech companies are hiring for right now. The pace is perfect, and the support is great.
I was initially intimidated by the math and complexity behind AI, but the trainers at Technovids explain things in such an accessible way. They break down everything from basic prompt engineering to complex integrations without losing you in the jargon. The session recordings and project materials are top-notch. If you are serious about becoming an AI Engineer, Technovids provides the perfect launchpad.
These answers cover what this page offers. Your written proposal sets out the terms for your own programme.
The standard RAG training runs 70 hours, delivered live online. A private team version can be shortened or extended, and the written proposal confirms its final duration.
Working Python, APIs and basic LLM concepts are recommended. Data handling and search familiarity help, but the confirmed cohort or proposal states the exact starting level.
The primary practice stack is confirmed for each delivery based on current integrations and access. The engineering principles apply across stores and frameworks, but equal hands-on depth in every product is not promised.
No. RAG can provide relevant external evidence, but retrieval, context use and generation can still fail. The course teaches separate retrieval and answer evaluation plus refusal and review patterns.
No. HSR Layout is the Technovids head office. When a public batch is scheduled, classes run live online on Zoom. The Technovids LMS gives you notes, assignments, lab guides, a batch discussion group, a certificate when you meet the requirements, and recordings uploaded within 24 hours that you can watch for three months.
No. Enquire for the next confirmed option, full timetable, prerequisites, lab stack, inclusions and fee.
Yes. Private training can use a safe client-relevant corpus and approved stack, delivered live online or onsite at the client’s workplace when agreed.
Tell us who the training is for, roughly how many people, and what you want them to do better at work. The Technovids team will scope it and reply with a written proposal.
Request received
Thank you — your request has been sent to the Technovids corporate training team. If you would rather speak to someone directly, the phone and WhatsApp details are at the top and bottom of this page.
2nd Floor, Chandrodaya Complex, 19/19, 24th Main Rd, near Hanuman Temple, Agara Village, 1st Sector, HSR Layout, Bengaluru, Karnataka 560102.
Please contact us before visiting the head office. The HSR Layout address is a head office, not a walk-in public classroom.